从前,人们讲批判性思维,讲的是带着谦逊的好奇和恰到好处的怀疑去面对新信息——听取不同的观点,形成自己的看法。这话现在依然成立,但自从我大量工作都交给 agent 去跑之后,日常里越来越没有什么东西会逼我做批判性思考了。对于已经全面拥抱 agent 工作流的工程师和产品人(同时开好几个 session 并行,并且预期模型会越来越强),我想先说明:我是这些工具的忠实粉丝。写这篇不是为了劝大家少用 agent。
Back in the day, critical thinking was taught as approaching new info with humble curiosity and a healthy dose of skepticism - take in different views, form your own opinion. Still true, but increasingly, nothing in my day-to-day forces critical thinking on me now that so much of my work runs through agents. For the engineers and product people who have fully bought into agentic workflows (running multiple sessions in parallel and expecting the models to improve), I'm here to say: I'm a big fan of these tools. I'm not writing this to advocate for less agentic workflows.
我的目的是:在一个什么都很容易甩给 agent 的世界里,帮你守住批判性思维。
My goal is to help you maintain critical thinking in a world where it's easy to offload anything to an agent.
过去,我们大部分认知上和审美上的加工,都发生在「提出问题」和「得到答案」之间的那段空隙里。如今这段空隙以秒计。你越用 agent 工作流,这件事就越难(只是难的方式和大家预想的不一样):模型越来越强,明显错误的比例越来越低。很多(大多数?)输出都会写得很好、基本正确,但它们不会逼你再看第二眼。
In the past, most of our cognitive and aesthetic processing happened in the space between question and answer. That space is now measured in seconds. The more you use agentic workflows, the more difficult it becomes (though not in the way I think people expected): as the models improve, the percentage of obvious errors is lower. Many (most?) outputs will be well-written and mostly correct, but they won't demand a second look.
就算你同时跑着很多个 agent,盯着输出的眼睛也还是只有你这一双。
Even if you are running many agents at a time, you still only have one pair of eyes on the outputs.
你得主动把批判性思维排进自己的一天,因为默认情况下,没有任何东西会替你做这件事。
You have to build critical thinking into your day, because by default nothing will do it for you.
之所以很难自我纠正,部分原因是 agent 工作流用起来很舒服。忙碌的一天里,拿到又快、又顺、又常常是对的答案,是一种享受——但也正因如此,你很容易放松警惕。
Part of the reason it's hard to self-correct for this is that agentic workflows are pleasant. Getting fast, pleasant, often-correct answers is refreshing in a busy day, but that's also why it's easy to relax your vigilance.
跟人聊这件事时,我会把它描述成一条光谱:
When discussing this with people, I describe it as a spectrum:
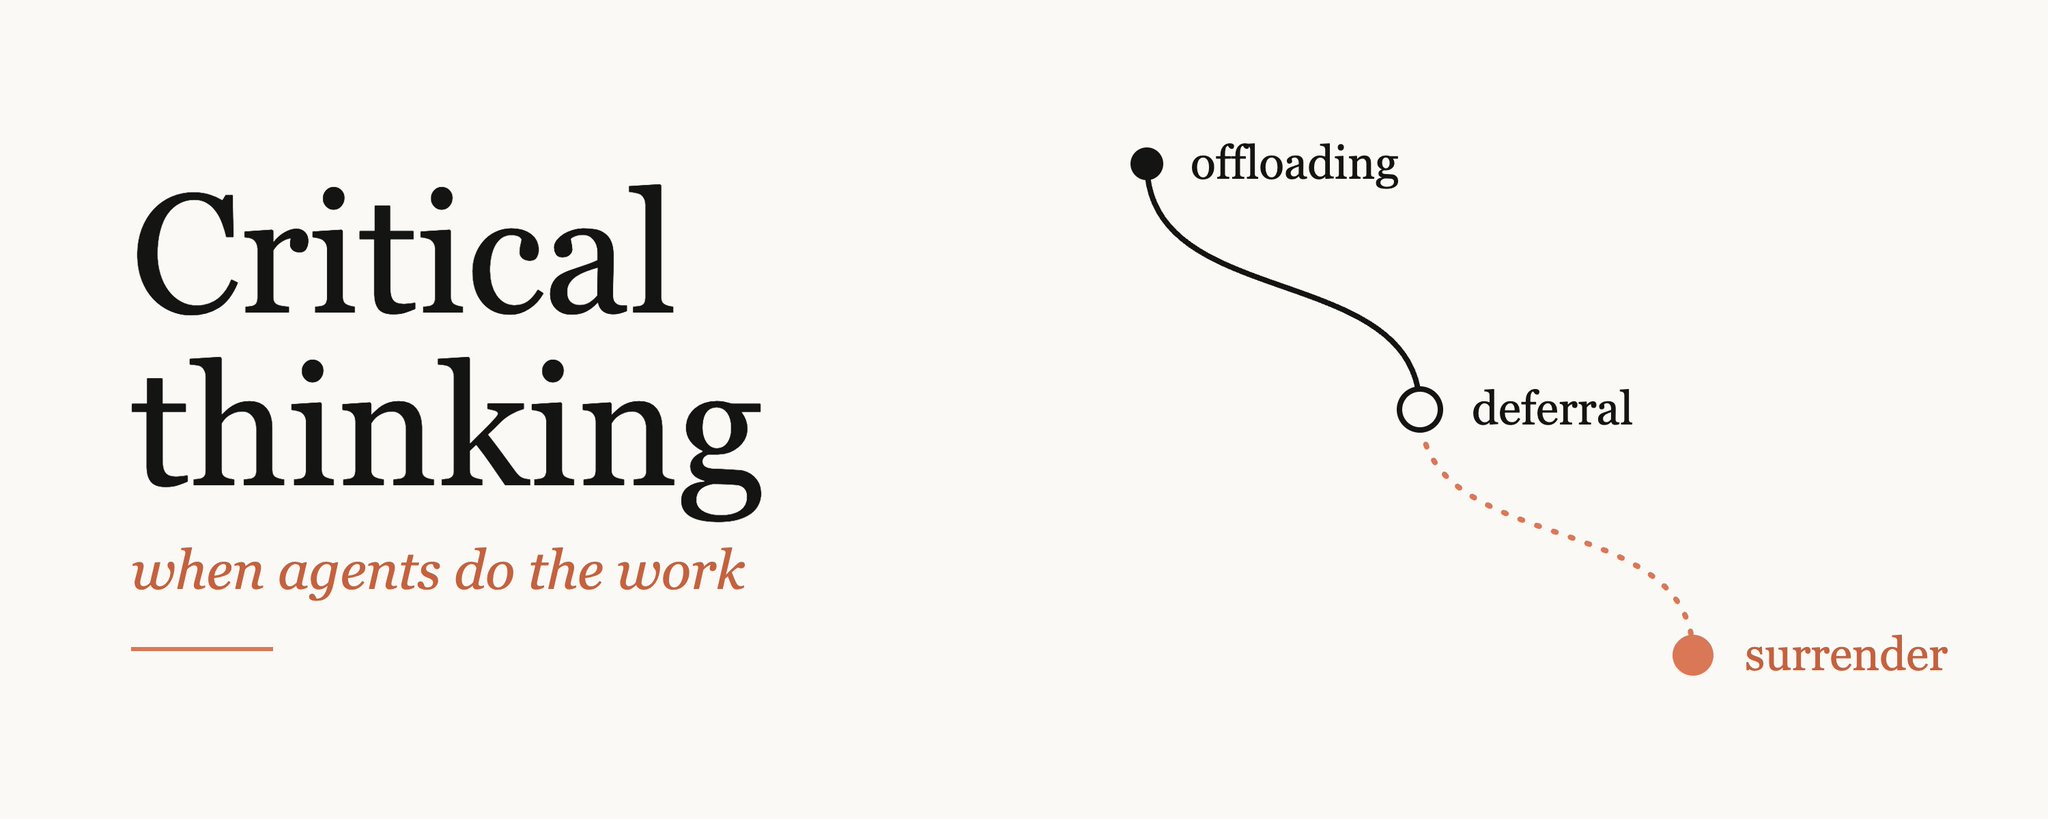
最上面是认知卸载(cognitive offloading):把任务委托给 AI,但结果的所有权还在你手里。我整天都在这么做,你也应该这么做。中间是听从(deferral):工具的输出变成了你新的输入,结果不再是一个有待检验的假设。最底下是认知投降(cognitive surrender):AI 的输出悄无声息地变成了你自己的,你觉得没有必要再去检查它。
At the top: cognitive offloading, the act of delegating tasks to the AI, but maintaining ownership of the result. I do this all day. You should, too. In the middle: deferral, where the output of the tool becomes your new input; the result has ceased to be a hypothesis. At the bottom: cognitive surrender - the AI's output quietly becomes your own, you feel no need to check it.
「认知投降」这个词是沃顿商学院的 Steven Shaw 和 Gideon Nave 提出来的。它恰好贴合我一直在观察到的现象:随着信任(或者说惰性)增加,人们会沿着光谱往下滑。这个过程很少被察觉,因为每一步都很渐进、看起来都很合理。上一个答案你认真读了,于是下一个你扫了一眼。再下一个你只看了个骨架。然后有人问你其中某一行是什么意思,你答不上来——就算让 agent 帮忙也答不上来。
Cognitive surrender is a term coined by Steven Shaw and Gideon Nave at Wharton. It fits neatly what I've been seeing: as trust (or laziness) increases, people drift down the spectrum. The transition is rarely observed, because the steps are each gradual and seem reasonable. You read the last answer well, so you skim the next one. You just scan the skeleton of the one after that. Then you get asked about a line and can't explain it, even with your agent's help.
这就是认知投降。认知债就是这么积累起来的。它通常是在你试图调用脑中对系统的心智模型、却发现那个模型根本不存在的时候才被发现的。Margaret-Anne Storey 写过它在团队里的表现:大家对一套共享的「系统理论」的理解在慢慢被侵蚀。我写过它在代码层面的对应物——理解债(comprehension debt,Jeremy Twei 造的词)。在当下,它完全不可见。代码库看着干干净净,测试全过。直到你要改动系统,才发现已经没有人懂它了。你只读了战略文档或需求文档的目录就签字通过,也是同样的道理。
That's cognitive surrender. It's how cognitive debt accumulates. It's usually discovered when you try to apply a mental model of the system and it doesn't exist. Margaret-Anne Storey has written about how this shows up in teams as an eroding understanding of a shared system theory. I've written about the code equivalent, comprehension debt (a term coined by Jeremy Twei). In the moment, it's completely invisible. The codebase looks pristine and the tests pass. It doesn't become obvious until you have to make a change to the system and realize that nobody understands it anymore. The same applies when you've read the table of contents of a strategy doc or spec and signed off on it.
先说清楚,我不是在要求不可能的事。一个大型现代代码库的完整心智模型,本来就不可能全部装在脑子里。Claude Code 团队公开说过,他们是按需重建理解的:需要搞懂某一部分时,就让 Claude 解释那一片,而不是把整个模型揣在脑子里。正如我之前写过的,这类债比大多数工程师以为的更容易还清。只要你能在需要时局部重建,就不必维持完整的模型。你只需要知道自己缺了什么。
To be clear, I'm not advocating for the impossible. It's impossible to maintain the full mental model of a large modern codebase. The Claude Code team has said publicly that they rebuild understanding on demand: when they need to understand a part, they ask Claude to explain that slice, rather than holding the full model in their heads. As I've written about before, this sort of debt is more recoverable than most engineers expect. You don't need to maintain the full model as long as you can rebuild it locally as needed. You just need to know what you don't have.
风险低的地方,放心全部委托出去。但如果一个问题的答案你解释不出来——哪怕借助 agent 也解释不出来——你就已经交出了所有权。
Where the stakes are low, feel free to delegate entirely. When you can't explain the answer to a question, even by way of your agent, you've ceded ownership.
这也不总是坏事。就在最近,我录一门课,要在三家评分差不多的酒店里挑一家当录制地点。我没时间把评论一条条看完,就把这个决定交给了 AI。效果不错,下次我还会这么干。但我不会在决定怎么投资我们家的钱、怎么给孩子提职业建议的时候这么做;工作上也不会——做什么、哪些改动会影响哪些用户、能不能安全上线。错了代价很小的事,放手交出去;后果要别人来承担的事,推理留在自己手里。
This isn't always a problem, either. Just recently, I was recording a course and had to select one out of three similarly-rated hotels to use as a recording location. I didn't have time to manually review all the reviews, so I delegated the decision to an AI. It worked, and I'd do the same thing again. However, I wouldn't do that when deciding how to invest our money, how to advise our kids on their careers, or at work: what we should build, what changes affect what users, whether it's safe to ship. Take the handoff where being wrong is cheap, keep the reasoning where others will have to deal with the consequences.
以前我不知道自己怎么想的时候,通常会回到一份很基础的问题清单:我怎么知道自己在解决对的问题?我怎么知道自己的解法是对的?有证据支持我的结论吗?我怎么知道自己做完了?大多数时候,这其实就是谁、什么、哪里、为什么、何时、如何。写出来幼稚得可笑,但它会逼你从一些原本会忽略的维度去想。如今,跳过这一切、直接问 agent「你觉得我该怎么做」实在太容易了。下面是我现在问自己的新版问题。
When I didn't know what I thought, I'd usually go back to a basic list of questions like these: How do I know that I'm working on the right problem? How do I know that I'm solving it the right way? Is there evidence that supports my conclusion? How do I know that I'm finished? Most times, this is just who, what, where, why, when and how. When written out, it looks absurdly child-like, but it forces you to think in terms of categories that you'd otherwise ignore. These days, it's too easy to simply skip all of this and ask your agent what it thinks you should do. These are the new versions of these questions that I ask myself now.
提问之前,我有没有先形成一个假设?在让 agent 做任何稍有分量的任务之前,我会先写下——哪怕只是在脑子里——我觉得答案可能是什么。猜得烂也没关系,有了新信息随时可以改主意。但一旦你读过一份写得很漂亮的回答,就很难再想象出别的可能了。如果你完全没有头绪,可以要求做一次 Thariq Shihipar 所说的盲点扫描(blind spot pass):把你知道的告诉模型,让它帮你找出你「不知道自己不知道」的东西。
Did I formulate a hypothesis before asking? Before I run an agent on any non-trivial task, I write down, even just in my head, what I think the answer might be. It's OK if it's a bad guess. You're always welcome to change your mind in light of new information. Once you've read a well-written response, though, it's hard to imagine any other possibility. If you have no guidance whatsoever, ask for what Thariq Shihipar calls a blind spot pass: give the model what you know and have it find your unknown unknowns.
我是在让它帮我思考,还是在把思考从我身上卸掉?两种都可以,只要你知道自己在做哪一种。
Am I asking it to help me think or to offload thinking from me? Both are OK, as long as you know which one you're doing.
要让这个结论是错的,得有什么为真?然后去查清楚。模型对自己有多大把握的自评,远不如一个你真能执行的测试有价值——所以给它一个测试。
What would have to be true for this to be wrong? Then go find out. A model's self-assessment of confidence is much less valuable than an actual test you can perform, so give it one.
我有没有从另一个角度听过反方观点?当我在一个多少有些开放的问题上持了强硬立场时,我会让不止一个模型去论证对立面,然后审阅输出,形成自己的看法。这样更费时间,但最后我对这个主题会懂得多得多。
Have I heard the counter argument from a different angle? When I've taken a hard stance on something that's somewhat open-ended, I'll ask more than one model to argue the opposite side, then review the output and form my own opinion. This takes longer, but I end up knowing much more about the subject.
当着要维护它的那个人的面,我敢不敢为它下注?这适用于代码,也适用于你交付的任何东西。我认为这就是「可问责」的标准线。
Would I bet on this in front of the person who has to maintain it? This applies to code and to anything else that you're delivering. I believe that this is the bar for answerability.
我已经不再练习什么了?可能是一些日常的调试。放掉一部分我能接受,但我希望那是有意为之。
What am I no longer practicing? Maybe it's some of the routine debugging. I'm OK with letting some of that go, but I want it to be intentional.
我最近写了很多关于验证的东西,因为我相信瓶颈已经从写代码转移到了「确定自己是对的」。当你给 agent 提供验证手段——无论是端到端测试、属性测试,还是真实的应用交互——它就能在你看任何东西之前,自己改一处、跑验证、读输出、再试一次。这就是 Boris Cherny 说的「给 Claude 一个验证自己工作的办法」,我认为这是拿到好结果最关键的环节之一。你不再逐行阅读,而是去搭这些循环、审阅证据。
I've been writing a lot about verification lately because I believe that the bottleneck has shifted from coding to being sure you're right. When you give an agent the means to verify what it's doing, whether that be by way of end-to-end tests, property tests, or by way of actual app interactions, it can make a change, run the verification test, read the output, and attempt again all before you've looked at anything. This is what Boris Cherny calls "give Claude a way to verify its work" and I believe that this is one of the most critical components of achieving great results. Rather than reading every line, you'll be building these loops and reviewing the evidence.
验证本身也可能被你「投降」掉。「有证据支持我的结论吗?」变成了「检查变绿了吗?」agent 让写测试变得极其便宜,你会看到大片的绿,但完全可能有一个通过的测试根本抓不到坏掉的功能。如果测试和功能犯了同一个错,它照样会过。而且一个绿勾只说明了一个性质。你太容易以为它覆盖了一切。
You can also surrender verification. "Is there evidence that supports my conclusion?" becomes "Did the check turn green?" Agents make it so cheap to create tests that you'll see a lot of green, and you could have a passing test that doesn't catch a broken feature. If the test is written with the same mistake as the feature, it'll pass. And a green check only conveys one property. It's too easy to imagine it covers everything.
检查变绿的时候,问问它证明了什么。然后再问它没证明什么。
When a check goes green, ask what it proved. Then ask what it didn't.
事先定义什么叫「已验证」,因为事后你会为任何结果找到合理化的说法。
Define "verified" upfront, because post-facto, you'll rationalize any outcome.
agent 工作的终点线应该是某种实打实的东西:一个通过的测试、一张截图、一段日志或 trace。这样「做完」的标准就是事实,而不是可以凭「看着像做完了」去解读(进而投降)的东西。当你收到 agent 的完成通知时,先别看总结,先去看它实际执行的命令片段和输出。
The finish line for agent work should be something tangible: a test passing, a screenshot, a log or trace. This ensures that the criteria for finishing the work is factual, and not up for interpretation (and surrender) based on something like "it looks like it's done." When you receive a finish notification from an agent, before you look at the summary, first review the code snippet of the command executed and its output.
Claude Code 也可以(在全新上下文里通过 subagent)对自己的工作做一轮自我批评,作为合理性检查。值得把它固化进循环里,让它每次都跑,而不是想起来才跑。我在最后还是会问一句「我漏了什么吗?」听起来很傻,但太多次了:我用前沿模型做完一个复杂功能,看过、审过,然后问「我漏了什么吗?」——它就会再找出两三件事。所以我每次都问。
Claude Code can also self-critique (via a subagent in a fresh context) its own work as a sanity check, and it's worth baking that into the loop so it runs every time, not just when you remember. I still ask at the end "Did I miss anything?" That sounds silly, but so often, when I finish some complex feature work using a frontier model, look at it, review it, and then ask, "Did I miss anything?" It will then come back with two or three more things. That's why I always ask.
当然,这些都不必成为常规;知道什么时候该深挖本身就是一种技能。我最喜欢的一条经验法则出自我们那篇关于 Claude Code 团队如何做 code review 的文章:「如果你说不出这些检查会漏掉什么,那就去要一次真正的 review,而不是一个快速的 approve。」
None of this needs to be the norm, of course; knowing when to go deep is a skill. My favorite rule of thumb from our write-up on how the Claude Code team does code review is: "If you can't say what the checks would miss, ask for a real review rather than a quick approval."
这在代码之外也适用。如果 agent 替你综合了五十通客户电话,或者做了一份竞品分析,就去核对其中几份原始材料,确认总结是准确的。你的建议依赖某个数字,就去核对那个数字是不是算对了。
This applies beyond code as well. If an agent has synthesized fifty customer calls for you, or a competitive analysis, check a couple of the source documents to make sure the summary is accurate. Check a number that your recommendation depends on to make sure it's being calculated correctly.
agent 让搭建验证变得很便宜。真正难的,是你知道好的验证长什么样。
Agents have made verification cheap to set up. What's difficult for you is knowing what good verification looks like.
假设 agent 给你提了一个 600 行的 PR。你大致看了看结构,没有逐行读。变量名看着合理,测试也过了,于是你批了。但在中间某个地方,一个事务边界的顺序被悄悄改了,或者某个你从没想过的边界情况的默认值被翻转了。你确实 review 过了——大概吧——但只 review 了你本来就知道会看到的东西。
Say an agent gives you a 600-line PR. You roughly look at the structure. You don't read every line. The variable names look reasonable and the tests pass, so you approve it. But somewhere in the middle there's a subtle ordering change in a transaction boundary, or a flipped default on an edge case you never thought about. You did review it, I guess, but only for what you already knew you'd find.
写代码和审代码是两种不同的技能,而且审着审着就会变成橡皮图章。所以读 diff 时,要当作它不是 AI 写的;然后越过 diff,去看 agent 做了哪些决定。在一个长 session 里,它会替你做很多小决定:默认值怎么设、什么算超出范围、两条需求冲突时它重新解读了哪一条。
Writing code and reviewing it are different skills, and there's a point where reviewing turns into rubber stamping. So read the diff as if the AI didn't write it, and then look past the diff at what the agent decided. Over a long session it makes a lot of small decisions for you: the defaults, what's out of scope, which requirement it reinterprets when two of them clash.
这些在一份「一切顺利」的总结里你一样都看不到,所以让它列出它做过的决定和假设。然后考考自己。随机挑几行,问:这一行是怎么回事?那一行呢?如果是文档,就合上它,试着凭记忆写出主要论点。有些人在长 session 里有个我很喜欢的习惯:让 Claude 写一份关于这次改动的报告,在末尾给你出一份小测验,规矩是「测验满分我才 merge」。
You won't see any of that in a summary that says everything went well, so ask it to list the decisions and assumptions it made. Then quiz yourself. Pick a few lines at random and ask, what about this line? What about that one? For a document, close it and try to write out the main argument from memory. Some have a habit I like for long sessions: have Claude write a report on the change, and then give you a quiz at the bottom, where the rule is "I only merge after I pass the quiz perfectly."
对你要上线的东西,要理解到足以为它辩护的程度。因为总有一天,会有人来问。
Understand what you're shipping well enough to defend it. Because at some point, someone could ask.
agent 也可以替你守护注意力。比如我有一个开源项目,会收到大量 pull request。我会用 agent 帮忙判断进来的是什么、哪些违背了我们的规范、哪些地方大概需要我亲自看。我很少让 agent 自己拍板,但它们能把范围缩小到我该关注的地方,这样我才能真正去想:这些改动是不是在用对的方式解决对的问题。
Agents can also guard your attention. For example, I have an open source project that receives a lot of pull requests. I'll use agents to help determine what's incoming, what's contrary to our guidelines, and where my attention is likely required. I rarely let the agents self-determine this, but they can narrow it down to where I should focus my attention, and then I can actually think about whether these changes are solving the right problem in the right way.
然后是量的问题,这一点你得对自己诚实。我把它叫作编排税(orchestration tax):agent 生成的东西,和你愿意署上自己名字的东西之间的差距。如果做完的活堆积的速度超过了你能消化的速度,那在解决这个问题之前,再开一个 session 也没用:要么把检查收紧,让需要你过目的变少;要么放慢。
Then there's volume, and you have to be honest with yourself about it. I've called this the orchestration tax. It's the gap between what your agents generate and what you'd feel comfortable putting your name on. If finished work is piling up faster than you can get through it, another session won't help until you've fixed that: tighten the checks so less of it needs you, or slow down.
当你产出的东西多过你能为之担保的,你就不是在 review 了。你是在祈祷。
When you're producing more than you can stand behind, you're no longer reviewing. You're hoping.
人的心智模型仍然在场,只是从中间挪到了两头。你的精力投在前端——任务描述和上下文,以及后端——审阅输出。这就是为什么好的输入对输出质量如此重要,我也把好的 prompting 看作一种批判性思维技能。
The human mental model is still involved, but instead of in the middle, it's at the front and end. You're putting your energy into the front-end of the task description and context, as well as the back-end of reviewing the output. This is why good input is so important to the quality of output, and I view good prompting as a critical thinking skill.
以前,如果你提了一个含糊的需求,会有人来质疑,然后你可能会意识到:「哦等等,这个我其实没想清楚。」agent 往往不会在这里拦住你。它会把你没说的部分自己补上,交还一个看起来已经完成的东西,尽管背后的想法依然是模糊的。我把这写成过意图债(intent debt):那些可能存在于并非你亲手写的产物里的隐含目标、约束和理由。和别的债不同,这笔债谁也没法替你还。意图必须来自你。
Historically, if you made a non-specific request, someone would challenge it, and you might realize, "Oh wait, I actually didn't figure this out." An agent often won't stop you there. It fills in what you left out and hands back something that looks done, even though the idea behind it is still fuzzy. I've written about this as intent debt, the implicit goals, constraints and rationale that may exist in artifacts you didn't write. Unlike other kinds of debt, nobody else can fix this one for you. The intent has to come from you.
你的 prompt 反映的是你对问题的理解。如果你没法把它表达清楚,那它在你自己脑子里可能也不清楚。
Your prompt is a reflection of your understanding of the problem, and if you can't express it clearly, it may not be clear in your own mind.
在求助之前,用你自己的话写一份需求简报。写清楚受众、不做的范围、以及「完成」的定义。如果改到第二轮还没到位,就别再微调了,重写你的 prompt。
Write your own request brief in your own words before you ask for help. Describe the audience, out-of-scope items, and the definition of done. When your second round of corrections hasn't got you there, stop tweaking and rewrite your prompt.
这件事你也可以让 agent 帮忙。我喜欢 Andy Clark 对「委托给 AI 系统」和与之协作的区分。在后一种情况下,你处在一个相互放大的良性循环里:你的 prompt 让输出更锐利,输出让你下一个 prompt 更锐利,也让你对问题的心智模型更锐利。如果事情还不清楚,就让 agent 针对它没搞懂的地方来采访你。如果你关掉 session 时,自己的心智模型变得更清晰了,那就是成功的标志。
You can have the agent help you with this too. I like the distinction Andy Clark makes between delegating to an AI system and collaborating with it. In the latter case, you're in a virtuous cycle of mutual amplification: your prompts sharpen your output, sharpen your next prompt and sharpen your mental model of the problem. If it's not clear, ask the agent to interview you about what it doesn't understand. If you close the session having refined your own mental model, that's a sign of success.
也要小心输入。每个 agent 都很容易只是把上一个 agent 的总结塞进自己的上下文,用不了多久,第三个 agent 就已经没读过原始文档了。
Also be careful about the input. It's easy for each agent to just pass the previous agent's summary into its context, and before long the third agent hasn't read the original document.
你还需要有自己对输出的标准。我在很多不同的创作媒介里玩过 AI,大部分成果从没拿出来给人看过,因为它们没达到我的标准。现在所有东西出来都排版漂亮、语气笃定,所以「精致」已经不再是一个有用的信号了。
You also need your own standards for output. I've played around with AI in lots of different creative mediums, and most of it never gets shown because it doesn't meet my standards. Things are all coming out nicely formatted and confident, so polish is no longer a useful signal.
AI 也许让生产变快了,但如果我不愿意把这份输出算在自己名下,我就不会把它拿出去。
AI may have made it faster to produce, but if I wouldn't feel comfortable attributing the output to myself, I won't output it.
当某样东西没达到你的标准时,把原因记进共享配置、hook 或测试里,让它别再发生。品味就是这样复利增长的;而把「为什么没入选」记下来,本身也是很好的练习。
When something doesn't meet your standards, note why in shared config, a hook or a test so that it doesn't happen again. That's how taste compounds, and noting why something didn't make the cut is good practice on its own.
如果你像我身边很多人一样看好这个领域的未来,那这个念头可能已经在你脑子里转了好几节了:再过一两年,我能发现的东西模型都能发现,那我何必还要维持这项技能?
If you're as bullish on the future of this space as many people around me are, you've probably had this thought for a couple of sections. In a year or two, the model will be able to detect what I'd be able to detect, so why bother maintaining the skill?
在很多「发现问题」的层面上你也许是对的,而且我自己也一直主张把越来越多的检测工作推给 agent。但我认为这件事仍然重要的原因是:说到底,总得有人为上线的东西负责。不管 AI 帮了多少忙,必须有一个人来承担责任。
You may be right on a lot of that detection, and I've been arguing for increasingly pushing detection to agents myself. But here's why I think it still matters: at the end of the day, someone is responsible for what ships. Regardless of how much AI helped, a human has to take responsibility.
某项任务该多信任 agent,这件事本身就是一个判断。保持校准的一部分,就是去审阅它的工作,因为模型会犯什么错一直在变。Anthropic 自己针对其工程师和研究员的研究就点出了这个陷阱,称之为「监督悖论」:「监督 Claude 所需要的,恰恰是那些可能因过度使用 AI 而退化的编码技能。」
The question of how much to trust an agent for any given task is itself a judgment call. Part of staying calibrated is reviewing the work, because what the models get wrong keeps changing. Anthropic's own research on its engineers and researchers calls out the trap as the paradox of supervision: "supervising Claude requires the very coding skills that may atrophy from AI overuse."
下面这些是对我最重要、而且更好的模型也解决不了的事:你在做什么,为什么值得做,它影响谁,你愿意牺牲什么?这些都是你必须自己回答的问题。agent 可以帮你把它们想透,我也希望它帮忙,但归根结底,它们还是你的。
These are some of the things that matter most to me and that a better model won't solve: what are you building, why is it worth it, who does it impact and what are you willing to sacrifice? Those are all questions you need to answer. An agent can be helpful in working them through, and I would like it to be, but ultimately they're still yours.
你可以把工作和大部分审核卸出去,但不能把问责卸出去。
You may offload the work and much of the auditing, but not the accountability.
这些不必一丝不苟地全做。挑适合你工作流的接进去就行。
You don't need to do all this rigorously. Just plug in what works for your workflow.
每周一次,不用 agent 写一点代码,或者做一件「要是忘了怎么做就糟了」的真事。(我管这个叫校准练习,但我不是在讲道德。)每月一次,写下你已经不再做的事,决定其中哪些你可以接受不做。我一篇旧博文里的一个问题至今依然成立:如果 AI 不存在,你会有多迷茫?
Once a week, write a bit of code without an agent, or do one real thing that would suck if you forgot how to do it. (I've called this a calibration exercise, but I don't mean it as a moral one.) Once a month, write down what you've stopped doing and decide which of those you're okay not doing. One question from an old blog post of mine remains as valid as ever: How lost would you be if AI didn't exist?
如果某样东西超出了你的理解,就去学它。我写东西时碰到一个没见过的说法,本可以 Google 一句话的解释塞进去。但我更愿意花点时间研究一下、真正弄懂它,这样我才能看清它在整体里的位置。
If something is above your comprehension, go learn it. If I'm writing and I run into a phrase I haven't seen before, I could Google a one-line explanation and include it. I prefer to do a little research to properly understand it, so I can see where it fits.
认真检查机器的产出是实打实的工作,假装它不是,就是团队最终不去做它的原因。它不是免费的,所以把它当作一个单独的条目排进计划,你才会真的做到。
Checking the machine properly is real work, and pretending otherwise is how teams end up not doing it. It isn't free, so schedule it as a line item and you'll actually get it done.
不再练习的技能会消失,而且可能比你以为的更快。那些你不愿放手的,就一直练下去。
Skills that you stop exercising are going to go away, and probably faster than you might guess. Keep doing the ones you're not willing to let go.
通过亲手运用那些重要的技能,让自己留在场上。你可以试试这一件事:提问之前,写下你觉得会发生什么;agent 做完之后,写下一件它没检查的事。告诉我这会不会改变你阅读输出的方式。独立思考。问更好的问题。为结果负责。
Keep yourself in the game by manually applying the skills that matter. One thing you could do: Before you ask, write down what you think will happen, and after the agent is done, write down one thing it didn't check. Let me know if that changes the way you read the output. Think independently. Ask better questions. Take responsibility for the outcome.